Tag: DH

  • Teaching LDA with the Topic Modeling Game

    Teaching LDA with the Topic Modeling Game

    The following post was featured as a Digital Humanities Now Editor’s Choice entry on April 2, 2013.

    In February, I visited Matthew Kirschenbaum’s #ENGL668K Introduction to Digital Humanities course at the University of Maryland, and I brought to class an activity that I had been mulling over in my own mind for a long time, called the Topic Modeling Game.  The game is designed to teach the basic principles of topic modeling with LDA through engaged, constructivist, and problem-based techniques.

    As I was learning about LDA myself, I realized that I was essentially playing this game in my head over and over again: following through how I thought LDA worked, learning where I made mistakes, revising my assumptions, and playing the game all over again.  When I went to write about the results of my topic modeling experiments for the Revising Ekphrasis project in my dissertation, what I discovered is that I really needed a way to explain topic modeling such that someone who had no knowledge of the methodology could read the results of my experiments and trust my conclusions.

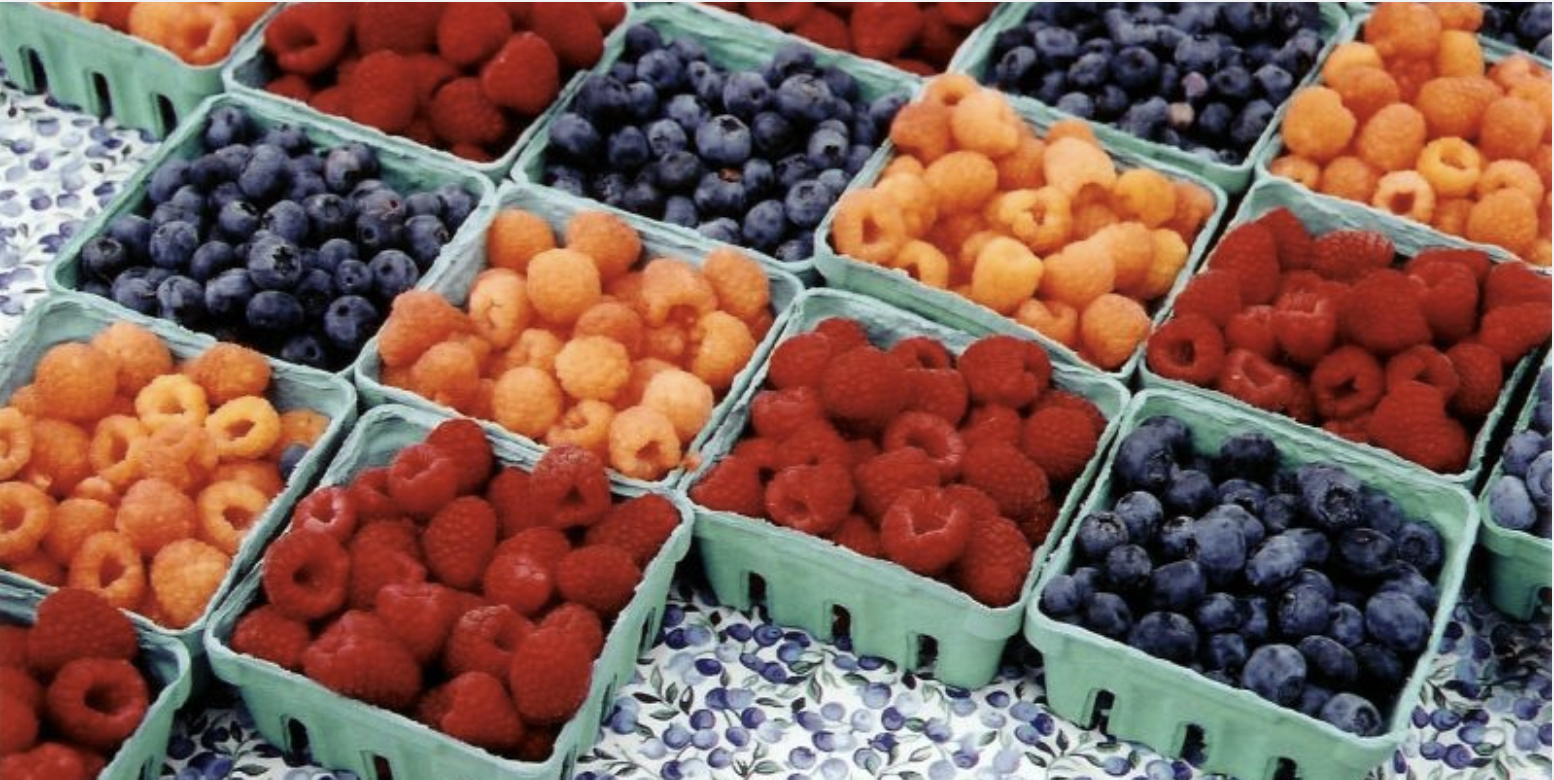
    That process led to a written explanation of LDA that will appear in a future article in the Journal of Digital Humanities.  In the essay, I create a hypothetical situation to explain the assumptions LDA makes about natural language texts in order to produce its results.  The example walks readers through the process of figuring out what produce is available at a farmers’ market that they have never been to themselves and asks the reader to consider the problem from a quantitative perspective.  When I created that explanation, I did it by playing this game in my head.  So, I thought, perhaps this could be an effective way of teaching LDA, as well.

    After tweeting something about the Topic Modeling Game, other DH instructors requested copies of the game.  I absolutely wanted to share, but I also wanted to learn from other teachers’ experiences.  More importantly, I wanted other new teachers to benefit from the experience of those who had already tried it.

    Meanwhile, there’s been a lot of conversation about the value of public, open repositories of data.  ProfHacker has had several recent posts about using GitHub to revise documents (see Getting Started with a GitHub Repository and Forks and Pull Requests in GitHub).  Also, Matt Burton presented a helpful introduction to Git at MLA 2013 in the Scaling and Sharing: Data Management in the Humanities special session #s586.

    What better way to share a lesson plan with peers, I figured, than to create a repository for it on GitHub, to invite others to use it and to ask that they share their results and add their changes and revisions back to the repository?

    As a result, I created a GitHub public repository for the Topic Modeling Game.  Currently, in the repository, there are two Word documents.  One includes instructions and background information for teachers.  The other is a rudimentary hand-out to use to begin the game as an in-class (face-to-face) assignment.  The instructor document includes a list of materials that could be used for the lesson, but I have not uploaded sheets of “sample words” to use—at least not yet.

    There is plenty of room to edit, improve, revise, innovate, and share.  The one thing that I do ask is that if you download and use the Topic Modeling Game, you contribute to the repository by adding lessons you have learned, revisions you made, and suggestions for improvement.

    So, bring your forks (again, you may want to read Konrad Lawson’s recent post on forking and pulling with git if you’re unfamiliar with the process) and dig on in.  I’m looking forward to hearing back from those who try it.
  • Curating a Network of Wood and Would

    Curating a Network of Wood and Would

    In my current research, I argue that Elizabeth Bishop’s poem “The Monument” represents a more democratic attitude toward aesthetic objects than what we see from her contemporaries Robert Lowell and John Berryman.  Eschewing the “tutelary” relationship between poet as teacher and reader as student, Bishop offsets her own position of power as the artist-creator by including the voice of a resistant, reluctant onlooker whose interrogations about what it is they are supposed to be looking at position the reader as the monument’s curator, one who must select between descriptions, views, depth, and purposes for the monument.  The monument’s physical presence is brought into being collaboratively between the two speakers who create it’s shape and it’s potential and the reader who must parse and prioritize the verbal network of the poem.  Furthermore, Bishop, who started writing “The Monument” in her Key West notebooks (see Barbara Page) after just having read Wallace Stevens’ Owl’s Clover, enters into public discourse about the relevance of public monuments (and by extension art) in a social, political, and economic climate in which people are suffering, nations are warring, and the realities of daily life seem to negate the place and purpose of art.  Sounds familiar, no?

    Bishop responds by arguing that monuments (and painting, and poetry, and sculpture) are significant because they are sites of “commemoration”–an interesting word choice because the word “commemorate” requires communal activity.  Unlike her friend Robert Lowell who uses the bronze relief by August Saint-Gaudens in Boston Commons to establish historical connection and significance for himself as an artist, Bishop imagines the monument as evolving to purpose rather deriving from it.

    Visualizing the poem as a network demonstrates how the speakers’ relationship to one another builds out of their discursive description of the monument.  In the networks below, each speaker is related to the monument through questions and description (recorded as the statements they make in the poem).  I have characterized those statements as grounding the monument in physical space, with tangible attributes, insisting on its materiality [repesented by blue lines] or on the other hand imagining the monument’s potential or possibility through questions, equivalences (is it this or that statements) and statements that intimate a metaphysical presence for the monument [in orange].

    <<image lost>>

    The networks are formed by matching each speaker up with with each statement made in the poem.  As a result, this is a “bimodal” network: one which takes actors and text and studies the relationship between them.  The relationship, represented by a line is further characterized as advancing the monument’s status as “wood” (a physical object belonging to the material, and therefore “real” world) and the word’s homophone “would” (a representation of possibility, potential, and by association the “imaginary” life of the mind).

    The reader as curator, then, must choose among the wood and the would–between the multiply rendered descriptions of the monument’s physical presence and its imagined potential, which is a new beginning itself, the shape of which could be poetry, painting, statue or monument, depending on choices the reader makes.

    Monument as Descriptive Network
  • Small Projects & Limited Datasets

    Small Projects & Limited Datasets

    I’ve been thinking a lot lately about the significance of small projects in an increasingly large-scale DH environment.  We seem almost inherently to know the value of “big data:” scale changes the name of the game.  Still, what about the smaller universes of projects with minimal budgets, fewer collaborators, and limited scopes, which also have large ambitions about what can be done using the digital resources we have on hand?  Rather than detracting from the import of big data projects, I, like Natalie Houston, am wondering what small projects offer the field and whether those potential outcomes are relevant and useful both in and of themselves as well as beneficial to large-scale projects, such as in fine-tuning initial results.

    My project in its current iteration involves a limited dataset of about 4500 poems and challenges rudimentary assumptions about a particular genre of poetry called ekphrasis—poems regarding the visual arts.  It is the capstone project to a dissertation in which I use the methods of social network analysis to explore socially-inscribed relationships between visual and verbal media and in which the results of my analysis are rendered visually to demonstrate the versatility and flexibility available to female poets writing ekphrastic poetry. My MITH project concludes my dissertation by demonstrating that network analysis is one way of disrupting existing paradigms for understanding the social-signification of ekphrastic poetry, but there are more methods available through computational tools such as text modeling, word frequency analysis, and classification that might also be useful.

    To this end, I’ve begun by asking three modest questions about ekphrastic poetry using a machine learning application called MALLET:

    1.) Could a computer learn to differentiate between ekphrastic poems by male and female poets?  In “Ekphrasis and the Other,” W.J.T. Mitchell argues that were we to read ekphrastic poems by women as opposed to ekphrastic poetry by men, that we might find a very different relationship between the active, speaking poetic voice and the passive, silent work of art—a dynamic which informs our primary understanding of how ekphrastic poetry operates.  Were this true and were the difference to occur within recurring topics and language use, a computer might be trained to recognize patterns more likely to co-occur in poetry by men or by women.

    2.) Will topic modeling of ekphrastic texts pick out “stillness” as one of the most common topics in the genre?  Much of the definition of ekphrasis revolves around the language of stillness: poetic texts, it has been argued, contemplate the stillness and muteness of the image with which it is engaged.  Stillness, metaphorically linked to muteness, breathlessness, and death, provides one of the most powerful rationales for an understanding how words and images relate to one another within the ut pictura poesis tradition—usually seen as an hostile encounter between rival forms of representation.  The argument to this point has been made largely on critical interpretations enacted through close readings of a limited number of texts.  Would a computer designed to recognize co-occurrences of words and assign those words to a “topic” based on the probability they would occur together also reveal a similar affiliation between stillness and death, muteness, even femininity?

    3.) Would a computer be able to ascertain stylistic and semantic differences between ekphrastic and non-ekphrastic texts and reliably classify them according to whether or not the subject of the poem is an aesthetic object or not?  We tend to believe that there are no real differences between how we describe the natural world as opposed to how we describe visual representations of the natural world.  We base this assumption on human, interpretive, close readings of  poetic texts; however, there is the potential that a computer might recognize subtle differences as statistically significant when considering hundreds of poems at a time.  If a classification program such as Mallet could reliably categorize texts according to ekphrastic and non-ekphrastic, it is possible that we have missed something along the way.

    In general, these are small questions constructed in such a way that there is a reasonable likelihood that we may get useful results.  (I purposefully choose the word results instead of answers, because none of these would be answers.  Instead the result of each study is designed to turn critics back to the texts with new questions.)  And yet, how do we distinguish between useful results and something else?  How do we know if it worked?  Lots of money is spent trying to answer this question about big data, but what about these small and mid-sized data sets?  Is there a threshold for how much data we need to be accurate and trustworthy?  Can we actually develop standards for how much data we need to ask particular kinds of humanities questions to make relevant discoveries?  In part, my project also addresses these questions, because otherwise, I can’t make convincing arguments about the humanities questions I’m asking.

    Small projects (even mid-sized projects with mid-sized datasets) offer the promise of richly encoded data that can be tested, reorganized, and applied flexibly to a variety of contexts without potentially becoming the entirety of a project director’s career.  The space between close, highly-supervised readings and distant, unsupervised analysis remains wide open as a field of study, and yet its potential value as a manageable, not wholly consuming, and reproducible option make it worth seriously considering.  What exactly can be accomplished by small and mid-scale projects is largely unknown, but it may well be that small and mid-sized projects are where many scholars will find the most satisfying and useful results.